AI & Product Consultant
How to automate the manual work of deciding what to post next
A creator who wants the next post to work has to know what is already working. Not in “the industry.” In the small circle they actually study, and on their own account. That means opening Instagram, TikTok, YouTube, X, LinkedIn, and a newsletter, reading captions and watching hooks, comparing likes to each person’s usual, and then deciding what to film or write today.
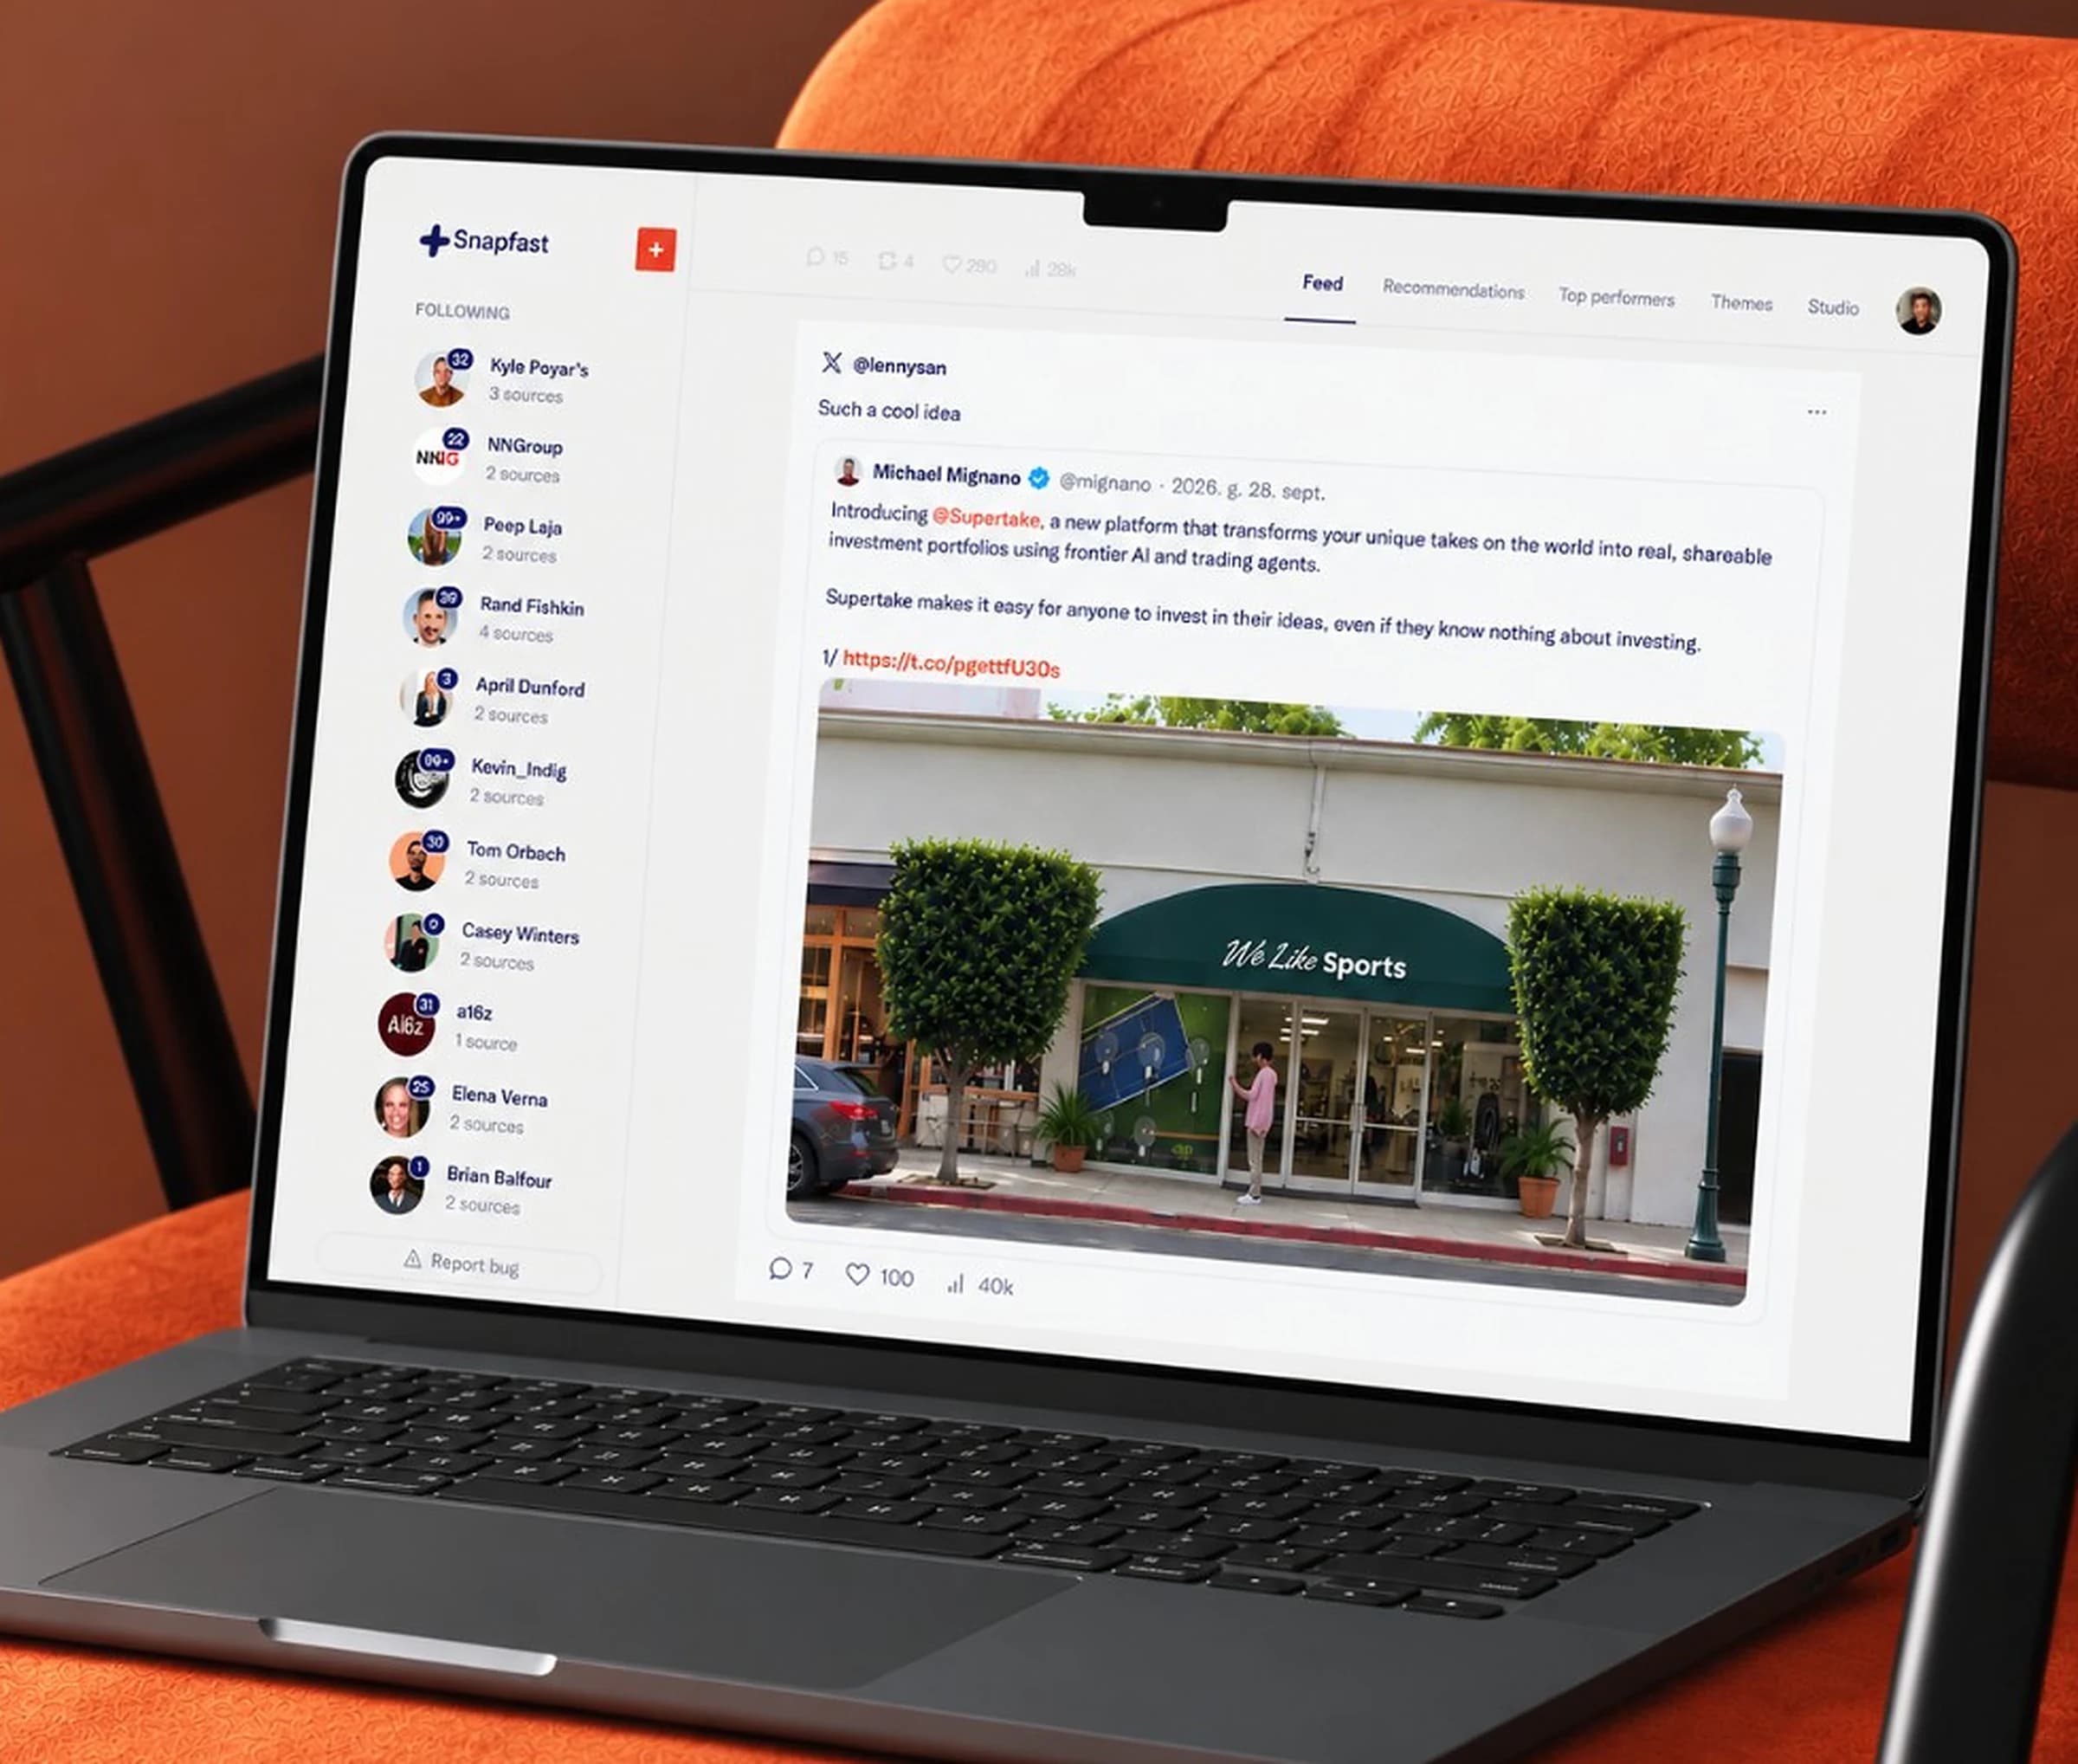
Snapfast does that job. You follow creators and, if you want, connect your own channels. The product archives their real posts with real numbers, then recommends the next thing you should post, with the posts that justify it still attached. A draft is one click from the card. Nothing is published for you.
Think of it as a factory for content decisions. Posts come in. Claims get extracted. Cards go out. The creator still decides what ships.
- 4
- cards on screen each day, each one tied to real posts
- 0
- posts published without the creator
- 1
- viral post is not a trend
The scale of the manual work
A working creator does not follow one account. They follow a circle: a few people slightly ahead, a few peers, sometimes a niche pack such as beauty educators. Each person posts on a different mix of platforms. A Reel with 48,000 plays can sit next to a LinkedIn post with 200 reactions and a YouTube video whose real argument is in the spoken track, not the title.
Before a tool, the workflow is a morning of tabs. Open each profile. Skim captions. Guess which hook is a pattern and which is a one-off spike. Save screenshots into a swipe file. Try to remember whether your own audience already rewarded that topic. Then stare at a blank draft and write something that sounds like the last viral post you saw.
The rules change by niche the way title rules change by state. A skincare educator’s “usual” likes are not an indie hacker’s. A 40× spike on a tiny account is a lottery ticket. A 1.5× lift against that creator’s own baseline is a pattern you can copy. Hashtags, “link in bio,” and “subscribe” lines look like content and are not. A silent Reel with a huge view count has a number and no topic.
Every day. Every platform. Skilled work, and almost all of it repetitive.
The goal
The job is not a better monitoring dashboard. Nobody wakes up wanting a creator-tracking tool. They wake up not knowing what to post, which idea is actually working, or whether a highlight-reel claim matches the posts.
The target is a daily brief: what to post, why, in which format, with the original posts attached. The creator spends their time on the judgment call: the take, the story, the on-camera delivery. The system does the reading.
Full autopilot was never the target. A post that goes out in someone else’s voice, with a fact the model invented, is worse than a blank page.
Human in the loop first
Other tools jump to “AI writes your content.” The failure mode is familiar: fluent posts, no receipts, and a user who cannot tell a grounded brief from a summary of marketing.
Snapfast keeps the person on the card. The model proposes. The creator approves, rejects, drafts, or ignores. Thumbs-down bans that topic. Thumbs-up is a signal to make more cards with those qualities, on a new topic. Ignoring a card is not a downvote. A busy week is not a verdict.
The only outcome that counts as proof is narrower than a click. The creator posted it, and it beat their usual engagement. Until that happens, the card is a hypothesis.
That rule shapes the product. Four cards on screen, two in reserve. A thumbs-down or “Draft this” promotes the next one. The system expands what it trusts only from behavior, not from a roadmap that assumes the model is already right.
A feed is not a decision
The first version of Snapfast was a different product: compare URLs, prep for a meeting. It reached 286 visitors and $7 over six months. Episodic pain does not bring people back.
The next version was closer: an evidence archive. Real posts, timestamps, links, engagement. No synthesis. That solved trust. It did not solve the morning. A library you can scroll is still a library you have to read.
Production-ready, for this job, means the archive is live, the recommendation is generated from that archive, and every sentence on the card can be opened. It means security on the connector, a real database of posts, and a draft that refuses to invent a personal story. A front end full of example cards is a prototype. A card that cites this week’s posts, in the creator’s language, on a channel they actually publish on, is the product.
The job was not “save time scrolling”
The early pitch was time. People would pay to stop jumping between X, YouTube, and Instagram.
They do not buy that. The pain that holds is the blank page: what to say today, grounded in what already worked for the people they study and for their own audience.
Users who have never had an evidence-backed brief cannot specify one in an interview. They ask for summaries, alerts, and “what’s trending.” Those are the tools they already know. The useful discovery was watching the job, then shipping a card they could reject.
Leadership of the product, in this case the founder using it, sets the feature list. Priority follows the decision, not the archive. Feed stays a receipt drawer, with no AI. Pulse names the week’s arguments. Daily cards are the post you can ship today. Studio writes only when someone opens a draft.
Ship the card, then learn from what they post
Hypothetical interviews produced a monitoring product. A live card produces a learning loop.
Each generation sees the last 30 days of cards: titles, thumbs and the reason, and what happened after: posted, drafted, or ignored. A rejected angle does not return. A loved quality comes back on a new topic. Recent drafts are in the prompt so the system does not re-issue a post already started.
Landing experiments run the same way. Hero, trial, and sign-in changed from real sessions, not from a persona doc. The operating rule is the same as on the card: put a working version in front of a person, then change it from what they do.
What AI does for every creator
Each step is one job, with a defined input and a structured output. The model never sees the whole internet. It sees this circle and this account.
Ingest and clean
Public posts land as events: caption or title, date, link, likes, comments, views. Boilerplate is stripped before any prompt: newsletter plugs, “link in bio,” promo codes. A shared CTA is not a theme. A post whose title and caption clean down to nothing is dropped from recommendations. It can still sit in the Feed as a picture and a number. It cannot be a trend.
Read only what the decision needs
Pictures are thumbnails for the human. The model does not watch the video. On the shortlist that might become a card, hook-frame text is read once and stored, and spoken words are pulled for Instagram, TikTok, and Facebook. YouTube uses the public caption track. Claims are extracted only from that transcript or on-screen text, close to the speaker’s words. Thin text returns fewer claims. Empty is allowed. Guessing is not.
Daily cards
Once per local day, the generator builds a set. The strongest card is an intersection: hot in the circle this week, and close to something this creator’s own audience already rewarded. The mix is roughly a quarter intersection, half circle-led, a quarter own-led. A circle-led card can ship when several creators share one concrete claim. A single viral post with no bridge to this person’s themes is skipped. Each card has a brief, a why-line with raw counts, one to three proof posts, and a format on a channel the creator actually uses. Topic can come from a YouTube video. If they only publish on Instagram, the format is still a Reel or a carousel.
Pulse
Same archive, weekly grain. Posts cluster into claims, not keyword soup. The model names a handful of concrete disagreements, “barrier damage from hot water,” not “skincare,” and keeps a post as evidence only when it is actually on that claim.
Studio
A draft is written only when the creator opens one. It sees the card, the cited posts, and a voice note. One post, first person, a position the source author did not already state. A personal fact that is not on file becomes a fill-in marker. It is never invented. The picture is still not sent to the writer.
Keeping the model honest
Reliability matters more than a clever take when the output is a recommendation someone might publish.
The generator does not free-associate a niche. If the archive is long-form interviews, the brief is an interview. An unrelated SaaS angle is discarded. Numbers in the why-line have to be the counts on the cited posts. A tiny baseline is shown as “144 vs usual 2,” not as a dramatic multiple. A card that says a video “said” something must map to an extracted claim. If it does not, the card is dropped.
Language is a gate, not a translation step. The brief is supposed to match the creator’s own posts. A mostly Cyrillic account does not get an English-only card.
Scope stayed narrow on purpose. The two libraries are the circle you follow and the channels you connect. There is no industry benchmark and no comment-body mining. Covering every edge of every platform on day one would have buried the decision in noise.
Tone is part of the gate. The why-line is a signal: who posted, the count, how recent, one clause that links the number to the ask. It does not restate the brief, and it does not scold. The same finding, written as a verdict, trains people to fight the tool. Written as evidence, it gives them something to check.
One pipeline, two doors
The recommendation logic does not fork per client. The web app and the connector read the same posts and the same rules.
The app is the daily surface: Home, Channels, Pulse, Feed, Studio. The connector is an MCP server. Claude, Cursor, or another agent can ask what a creator’s strategy looks like, what the circle is arguing about this week, or for a draft with receipts. Adding a capability is another tool on that server: list creators, pull a transcript, create a draft. Not a second copy of the prompts.
The model does not receive database credentials. A person connects with Snapfast sign-in, or with a token from Settings. The token resolves to that user’s archive. Read tools return their circle and their channels. Write tools stop at a draft. Publish stays a human action.
Long work stays off the critical path of browsing. Polling fills the archive in the background. Recommendations generate for the local day, then sit. Speech and hook-frame reads run on the shortlist, and the result is stored so the next run does not pay for the same frame twice.
AI across the delivery cycle
The product is an AI system, and the way it is built is an AI workflow. One person, with Cursor on the codebase, ships ingest, ranking, prompts, and the marketing page as the same loop: change the rule, watch a real card, tighten the gate that let a bad card through.
That is a small team’s pace because the steps are separated. A new platform is a new ingest shape. A new honesty rule is a filter in front of the shelf. The prompt does not grow a new personality for each one.
Planning
The prompt contract. Each card part has a source it must come from.
Design
The card itself: brief, evidence, proof, format.
Backend
The drop list: empty text, ungrounded claim, language mismatch, banned topic, platform the creator does not use.
Frontend
The shelf, the thumbs, and Draft this.
Testing
A card you would not post. If the why-line could have been written without the cited post, the card fails.
What is live
The loop runs in the product. Follow a creator, and their public posts accumulate with counts and links. Connect a channel, and your own posts become the baseline. Home and Channels serve the day’s cards. Pulse names the week’s claims. Feed keeps the chronology with no synthesis, so a number can be checked. Studio writes a draft from the card and the cited text. The same archive is available to an external agent through the connector at snapfast.ai/mcp.
The system was not a rebuilt social network. An archive was added, then a recommendation layer on top of it, then a draft that cannot outrun the archive. People move toward it one card at a time. A rejected card is data. A posted card that beats their usual is the result that matters.
What this project teaches
Human in the loop first
Propose the post. Let the creator verify. Treat “posted, and it beat their usual” as the bar for a win. Thumbs are a prior. They are not the outcome.
Ship the decision, then learn
A feed and a meeting-prep tool taught the wrong lesson. A card someone can reject teaches the job. People who have never seen a receipt-backed brief cannot specify one in an interview.
Build for a moving brief
The product was a meeting tool, then an archive, then a daily recommendation. The archive stayed. The sentence on the card changed. A pipeline that reads posts and emits a structured brief can absorb that. A prototype wired to one pitch cannot.
Decompose the task
Ingest, clean, extract a claim, rank, explain, draft. One job per step. When the words are missing, return nothing. Open-ended “what should they post” reasoning is how ungrounded cards ship.
Show the number, do not deliver a verdict
“556 likes yesterday” can be checked. “This is the winning strategy” cannot. The same evidence, written as a signal beside the original post, is what people will use.
Use AI to build the gate, not only the sentence
Code generation makes the loop fast. The durable work is the filter that drops a fluent card when the claim is not in the source.
Access is part of the first version
The connector sees one user’s archive through their sign-in or their token. The model never holds the keys to the database. A draft is the furthest write. Publishing stays with the person.